06b / Caching
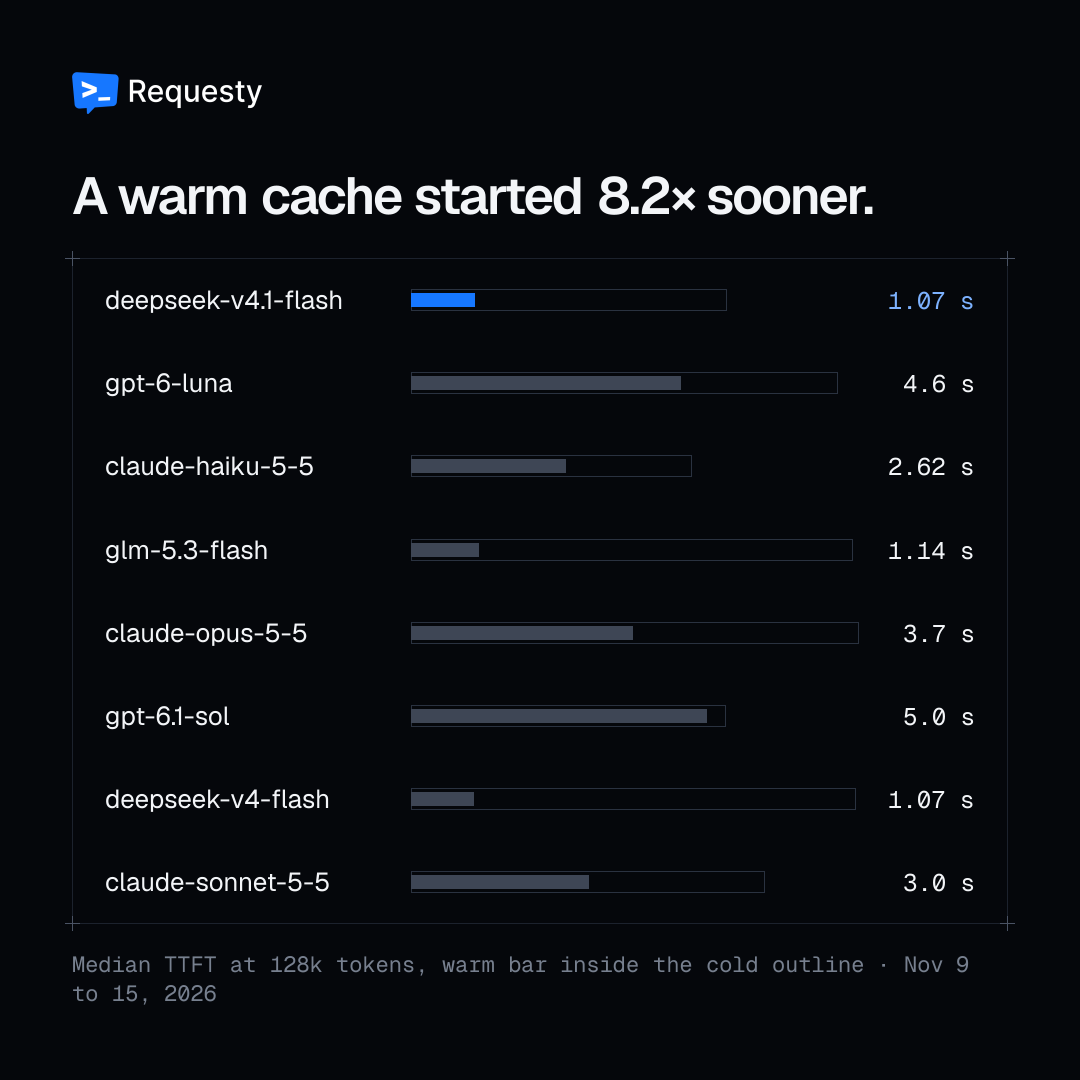
A warm cache started 8.2× sooner.
On the Requesty gateway in week 46 (Nov 9 to 15, 2026), deepseek-v4.1-flash prompts over 512k tokens reached the first token 8.2x sooner when more than half of the input came from cache: 2.65 s against 22 s at the median.
Below about 8k tokens the cache barely changes the wait. Above 32k it is the difference between an agent that feels instant and one that stalls, so keep the start of long prompts stable.
Turn on auto caching →- Value
- 8.2× cold vs warm median time to first token, deepseek-v4.1-flash, prompts over 512k tokens
- Period
- Nov 9 to 15, 2026 (UTC)
- Compared with
- Nov 2 to 8, 2026
- Source
- Requesty gateway, shares, rates, ranks and latency only
Share
Post this chart
What a warm cache buys: deepseek-v4.1-flash on Requesty last week, prompts over 512k tokens, 22 s to the first token cold and 2.65 s warm. 8.2x sooner (Nov 9 to 15). requesty.ai/data/weekly/2026-w46/warm-cache
On desktop: copy the image, open X, paste. The text is filled in for you. On a phone, Share sends the image and text to the app in one go.
| Name | This week | Last week |
|---|---|---|
| deepseek-v4.1-flash | 1.07 s | 5.3 s |
| gpt-6-luna | 4.6 s | 7.2 s |
| claude-haiku-5-5 | 2.62 s | 4.7 s |
| glm-5.3-flash | 1.14 s | 7.4 s |
| claude-opus-5-5 | 3.7 s | 7.6 s |
| gpt-6.1-sol | 5.0 s | 5.3 s |
| deepseek-v4-flash | 1.07 s | 7.5 s |
| claude-sonnet-5-5 | 3.0 s | 6.0 s |
More from week 46
New charts every Monday
Follow by RSS →For agents
- Markdown
- /data/weekly/2026-w46/data.md
- Latest
- /data/weekly/latest.json
- llms.txt
- /data/weekly/llms.txt
# Any week URL returns Markdown when asked for it
curl -H "Accept: text/markdown" \
  https://www.requesty.ai/data/weekly/2026-w46