W45W46 →
DraftFigures need sign-off before this week is published.
07 / Caching
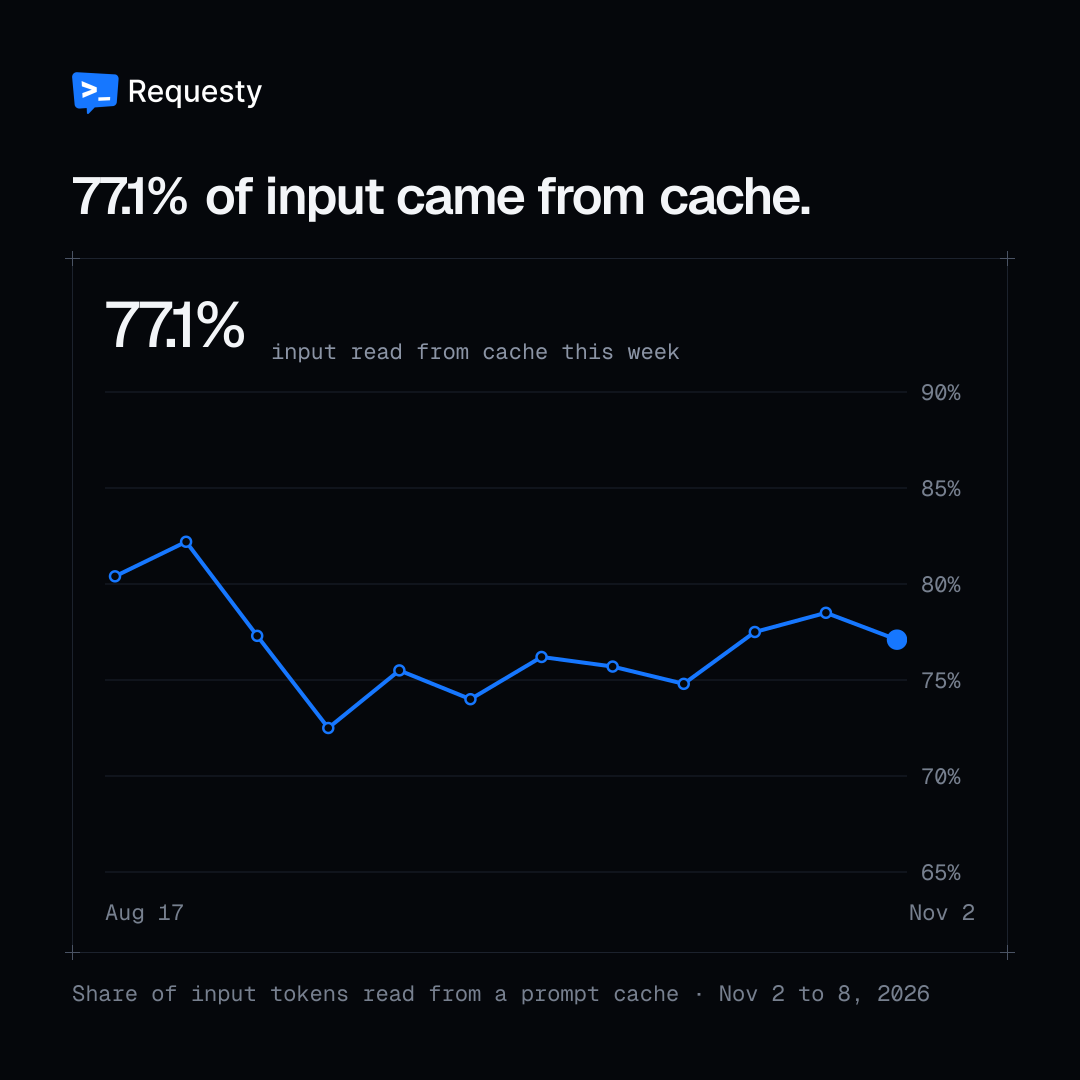
77.1% of input came from cache.
77.1% of input tokens through the Requesty gateway in week 45 (Nov 2 to 8, 2026) were read from a prompt cache; models read 46 input tokens for every output token.
Input is most of the bill for agent workloads, and the cache decides what that input costs. Compare models on what you pay after caching, not on the list price for output.
Turn on auto caching →- Value
- 77.1% of input tokens
- Period
- Nov 2 to 8, 2026 (UTC)
- Compared with
- Oct 26 to Nov 1, 2026
- Source
- Requesty gateway, shares, rates, ranks and latency only
Share
Post this finding
Preview on X1080 × 1080
>_
Requesty
@RequestyAI
77.1% of input tokens on Requesty last week were read from a prompt cache (Nov 2 to 8). Models read 46 input tokens for every token they wrote. Output price is the smaller part of most bills. requesty.ai/data/weekly/2026-w45/prompt-cache
Platform
Image
Text
The link to this finding is added for you215 / 280
On desktop: copy the image, open X, paste. The text is filled in for you. On a phone, Share sends the image and text to the app in one go.
| Week of | Input read from cache |
|---|---|
| 2026-08-17 | 80.4% |
| 2026-08-24 | 82.2% |
| 2026-08-31 | 77.3% |
| 2026-09-07 | 72.5% |
| 2026-09-14 | 75.5% |
| 2026-09-21 | 74.0% |
| 2026-09-28 | 76.2% |
| 2026-10-05 | 75.7% |
| 2026-10-12 | 74.8% |
| 2026-10-19 | 77.5% |
| 2026-10-26 | 78.5% |
| 2026-11-02 | 77.1% |
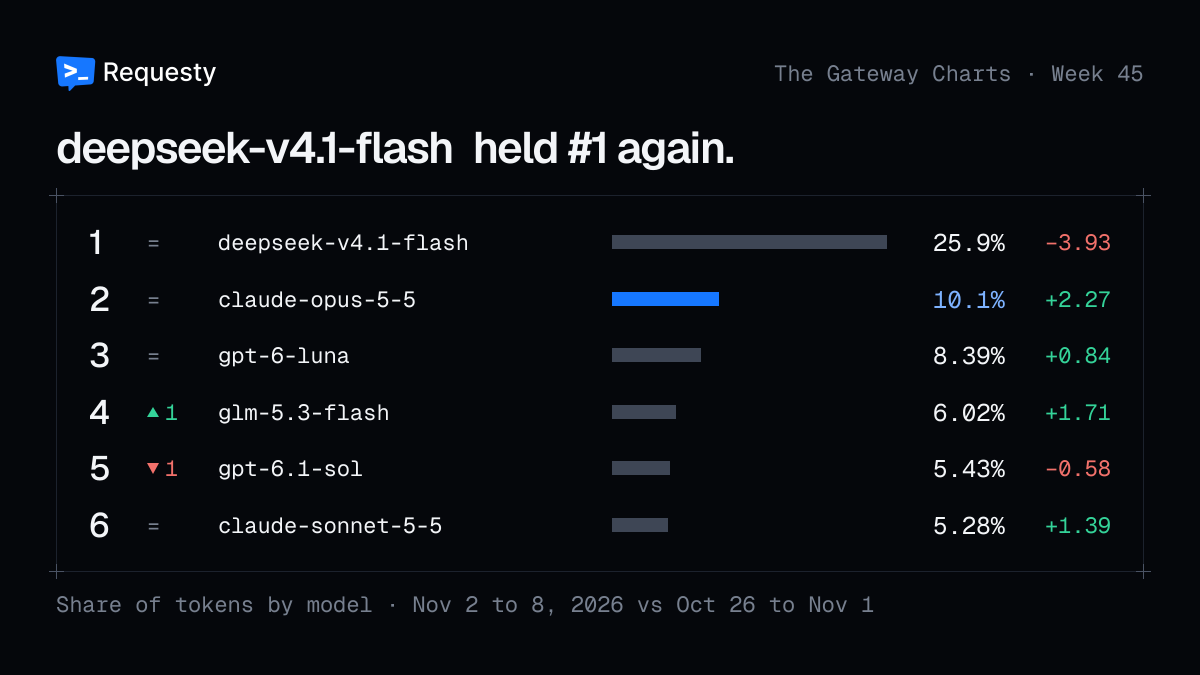
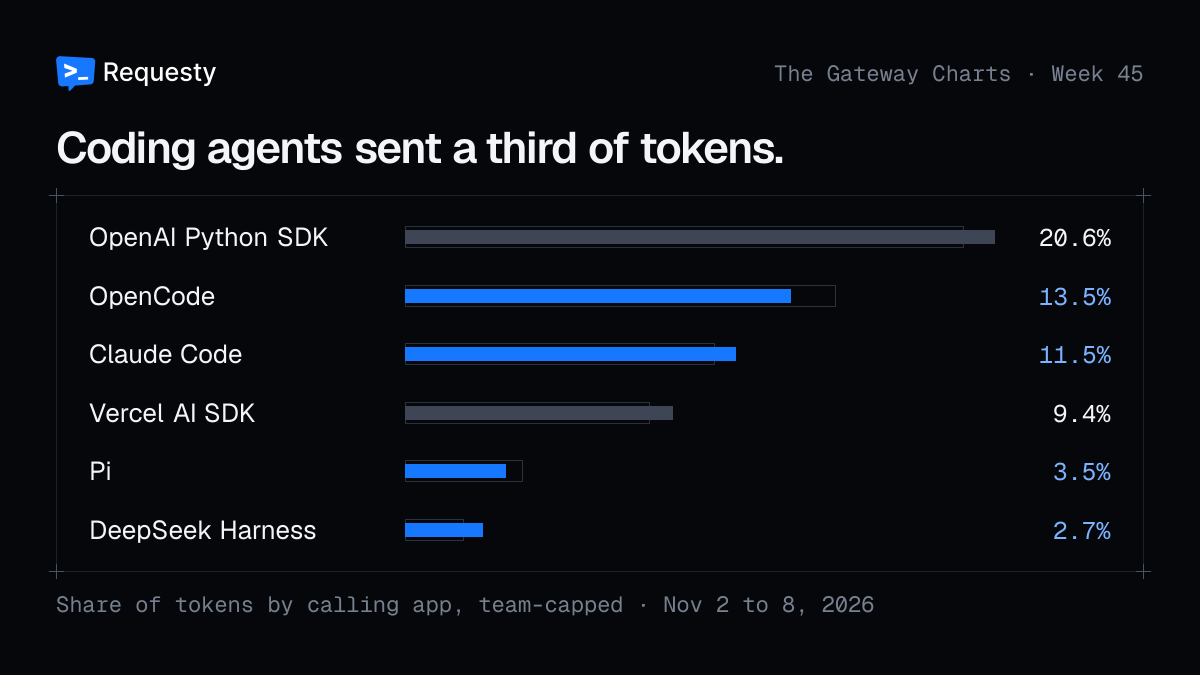
More from week 45
New charts every Monday
Follow by RSS →For agents
- Markdown
- /data/weekly/2026-w45/data.md
- Latest
- /data/weekly/latest.json
- llms.txt
- /data/weekly/llms.txt
# Any week URL returns Markdown when asked for it
curl -H "Accept: text/markdown" \
https://www.requesty.ai/data/weekly/2026-w45Source: Requesty, The Gateway Charts, week 45 (Nov 2 to 8, 2026). CC BY 4.0.